Introduction
For a very long time, we have been using images to store vital information, be it screenshots of some important text or tabular data or Excel dashboard analysis. Yet extracting that information without any human help was almost impossible for a long time. In the past few years some techniques were introduced like OCR (optical character recognition). However, this approach had its limitations as it gave some results but was far from the accuracy and efficiency that we needed.
As technology and business evolved, images started getting more complex due to higher data density, variation in lighting, and sheer diversity of visual content, which presented significant hurdles. This underscored the fundamental difficulty of bridging the gap between raw visual data and actionable insights, setting the stage for the transformative impact of AI.
Rise of AI in Computer Vision
The introduction of artificial intelligence, particularly the rise of computer vision techniques, marked a significant turning point in image analysis. Advanced approaches were introduced for specific tasks such as object detection, facial recognition, and basic scene understanding. Each organization started using these applications for analyzing images and integrating them to improve efficiency and reduce costs.
However, these approaches were far from working completely independently. They were built to perform specific tasks and could not generalize to others. They often required supervision by a highly trained engineer. Then came the rise of LLMs, which brought a huge shift in how we interact with AI models.
Large Language Models are AI systems that can understand, generate, manipulate, and respond in human language. Because they are trained on vast datasets, they are highly capable and can process and understand information from multiple modalities like text and images. This capability has fundamentally transformed image analysis, making it more accessible and powerful.
Now with the help of these LLMs, anyone can upload an image and generate detailed textual descriptions, extract specific information, or even generate creative content based on an image. Researchers can quickly analyze large datasets of medical images to identify patterns. Businesses can automate the extraction of data from visual reports and documents. Multimodal LLMs have significantly improved the accuracy and efficiency of image analysis.
Problem Statement
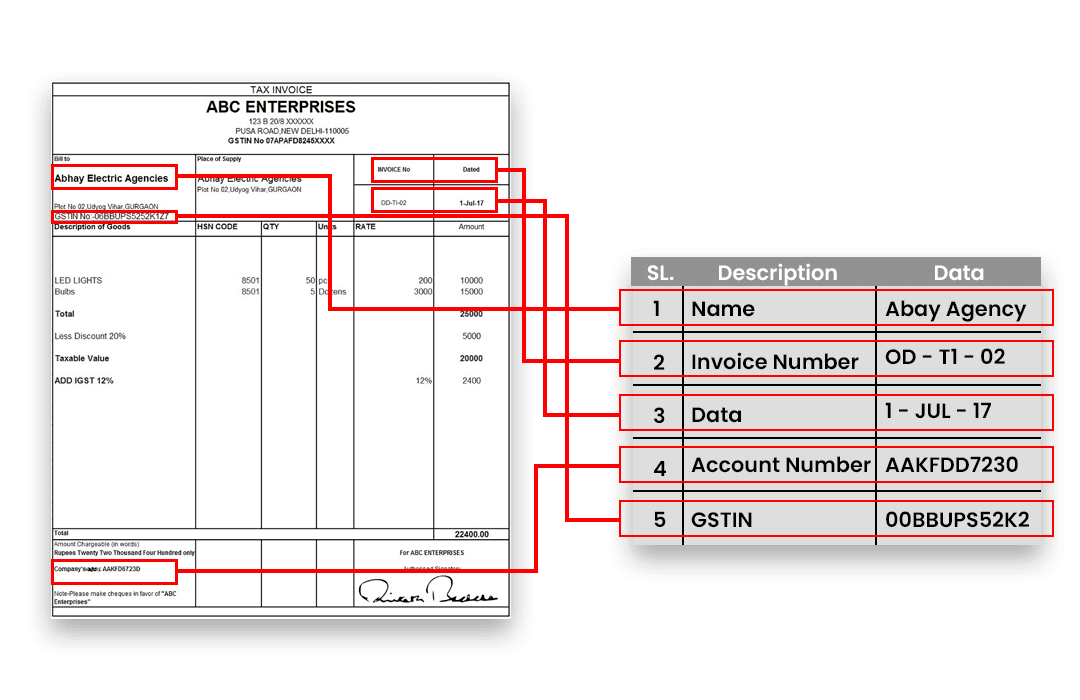
Our research focused on using the capabilities of multimodal LLMs to develop an approach for getting invoice details in proper JSON format. Invoices contain a number of products, their prices, and other details, and we aimed to fetch each detail from invoice images.
The core idea behind our approach is to guide LLMs with advanced prompt engineering techniques to generate structured text outputs that accurately and comprehensively describe the content of an image, bridging the gap between visual and textual information.
Step by Step Guide
Importing Libraries
import os
import base64
import google.generativeai as genai
from pathlib import Path
import json
from PIL import Image
import io

genai.configure(api_key="Your_API_Key")- os: Used to interact with files from your local system
- base64: Helps to encode and decode binary data into ASCII format
- genai: Provides access to Gemini generative AI models
- pathlib: Offers an object-oriented way to interact with files and directories
- json: Helps in dealing with JSON data for structured data exchange
- PIL: Library for manipulating and dealing with images
- API key: Enter your Gemini API key for authentication
Creating a Function to Analyze the Image
def generate_data(image_path, prompt):
    try:
        with open(image_path, 'rb') as img_file:
            image_binary = img_file.read()

        # Determine the image mime type
        image = Image.open(io.BytesIO(image_binary))
        image_format = image.format.lower()
        content_type = f"image/{image_format}"

        # Encode the image as base64 for processing
        image_base64 = base64.b64encode(image_binary).decode('utf-8')

        # Configure the Gemini model
        generation_config = {
            "temperature": 1,
            "max_output_tokens": 2000
        }
        model = genai.GenerativeModel(
            model_name="gemini-2.0-flash",
            generation_config=generation_config,
        )

        # Start a chat and send the image for processing
        chat = model.start_chat()
        response = chat.send_message([
            prompt,
            {
                "mime_type": content_type,
                "data": image_base64
            }
        ])
        result_text = response.text
        return result_text

    except Exception as e:
        return {
            "error": f"Error processing image: {str(e)}",
            "details": str(e)
        }
The function takes two parameters: the image path and the prompt. First, it determines the image MIME type to pass as context to the LLM. Then it converts the image to base64 format, since we cannot pass an image directly and need to convert it to data that holds the image information.
The model parameters are then defined. Temperature controls how varied the response is, and max_output_tokens defines the maximum output length. Make sure to adjust max_output_tokens correctly, otherwise if the response surpasses this limit you will get an incomplete generation. The whole function is wrapped in try/except to ensure errors are presented in a readable and understandable manner.
Prompt Engineering
prompt = """
    Analyze this invoice image and extract the following information in a structured format:
    1. Total number of products/items
    2. Each product name with its corresponding cost
    3. Subtotal amount (if available)
    4. Tax amount (if available)
    5. Total invoice amount

    Return the information in a structured JSON format with the following keys:
    {
      "total_products": number in integer,
      "products": [
        {"name": "product_1 name", "price": price of product one},
        {"name": "product_2 name", "price": price of product two}
      ],
      "subtotal": number,
      "tax": number,
      "total_amount": number
    }

    Only respond with the JSON object, nothing else.
    If any information is not found, use null for that field.
    Critical: Only give output in the above format and no explanatory text.
    """
To improve accuracy and reliability, we implemented iterative and advanced prompting. Iterative prompting means guiding the LLM through clear steps, breaking down complex tasks into manageable subtasks. Instead of asking the LLM to directly generate the final analysis, we ask it to first perform steps that break down the main goal.
We also provide a sample output format so the model knows exactly what structure is expected. We had to ensure we were not providing overly lengthy prompts, as lengthy prompts significantly increase the chance of the model hallucinating or giving garbage responses.
Our research showed it is important to balance clear instructions, examples, and relevant information while keeping the prompt concise. The "Critical" tag at the end draws the LLM's attention to the most important requirement: maintaining the desired output format.
Generating Results
image_path = r"Image_path/img.png"  # Enter your image path
result = generate_data(image_path, prompt)
print(result)
In this step, we call the function by providing the image path and prompt as parameters. The output is well-structured and accurate, matching the desired JSON format.
Sample Output
{
  "total_products": 3,
  "products": [
    {"name": "Projecting", "price": 50.00},
    {"name": "Develop", "price": 680.00},
    {"name": "Analysis", "price": 105.00}
  ],
  "subtotal": 835.00,
  "tax": 150.30,
  "total_amount": 901.80
}
Model Comparison
For this approach, we experimented with two different models: Gemini 1.5 Pro and Gemini 2.0 Flash. The aim was to assess how accurately each multimodal model manages to extract information from invoice images. Each model was tested against the same prompt.
- Gemini 2.0 Flash: Delivered the most consistent results, especially when the image was complex or contained a lot of information. This model consistently produced the desired results in the correct format.
- Gemini 1.5 Pro: Matched the accuracy of Gemini 2.0 Flash in terms of output quality but was slightly less consistent in its response format.
Our comparative analysis highlighted the strengths and weaknesses of each model, providing valuable insights into their suitability for different image analysis tasks. Gemini 2.0 Flash emerged as the top performer, demonstrating superior accuracy, reliability, and consistency.
The Future of Image Analysis and AI
The way AI and LLMs are evolving, we can say with confidence that we have a promising future where images become as readily accessible and interpretable as text. The time is not far where the ability of these AI systems to analyze images and generate minute details may surpass human capabilities in certain domains.
Future LLMs will not only identify scenes but also grasp the emotional and cultural context behind them. Imagine an AI analyzing a painting that not only describes the visual elements but also correctly identifies the thought process and intent of the artist. This level of contextual understanding will unlock new possibilities in art history, cultural preservation, and creative content generation.
Combining image analysis with other AI fields like natural language processing and audio analysis will lead to stronger and more adaptable systems which can transform the world completely.
At Cogninest AI, we specialize in helping companies build cutting edge AI solutions. To explore how we can assist your business, feel free to reach out to us at team@cogninest.ai.
- LLM
- image to text
- multimodal AI
- Gemini
- invoice extraction
- prompt engineering
- computer vision
- document AI
- GPT-4V